A common architectural pitfall in production AI agents is routing every interaction to a single monolithic frontier reasoning model. During early development, piping prompt triage, entity extraction, JSON validation and drafting through a top-tier frontier model feels convenient. However, when an enterprise agent scales to thousands of daily events across complex workflows, that single-engine approach hits severe operational bottlenecks: elevated latency that degrades user experience, and unsustainable token invoices. The path to robust production performance is not abandoning frontier reasoning, but designing dynamic LLM model routing production architectures that pair fast, typed classifiers with deep reasoning cores.
Illustrative synthetic scenario: the architecture patterns and operational metrics in this guide demonstrate design choices for multi-step workflow agents rather than specific client records or verified organizational benchmarks.
The Single-Model Trap: Token Costs, Latency and Pipeline Fragility
In a standard agent loop, an incoming request rarely translates into a single model completion. An autonomous workflow agent typically runs through multiple internal steps: classifying visitor intent, checking for required parameters, extracting structured entities, querying enterprise databases, and formatting downstream actions. Delegating every subtask to a large frontier model imposes a steep tax on trivial computation.
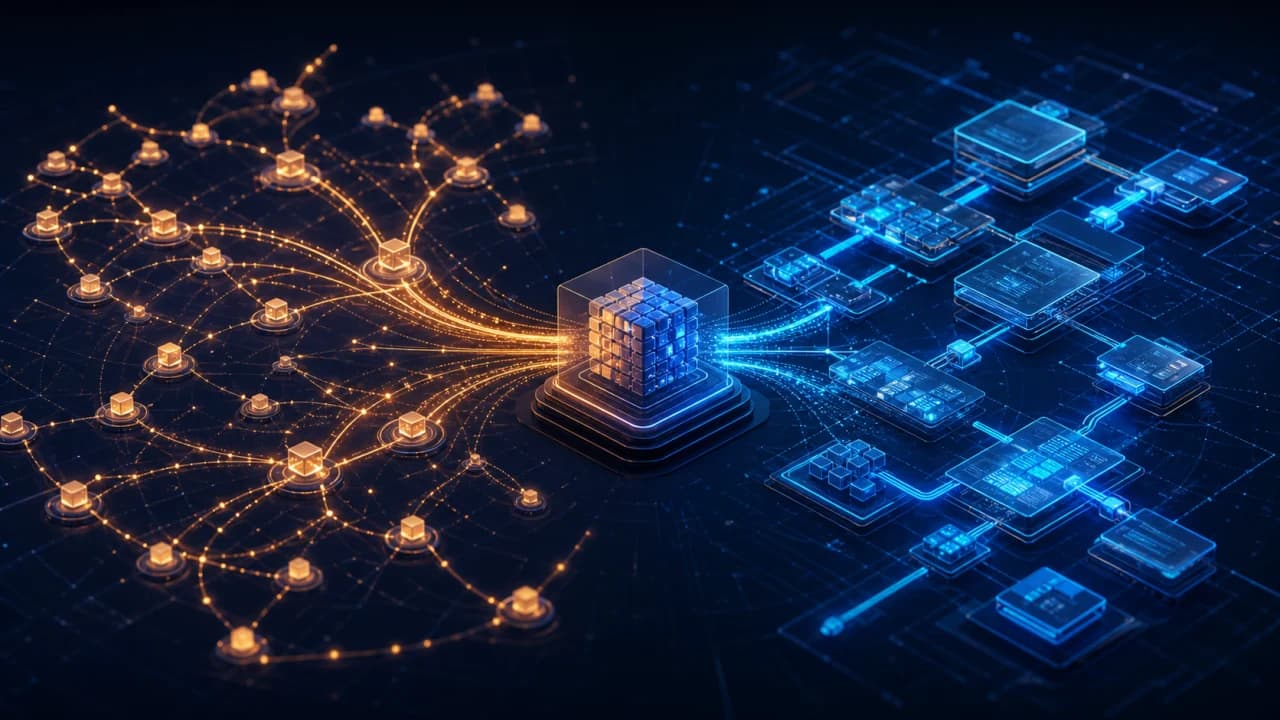
One frontier model for every subtask. Simple classification and parameter parsing incur multiple seconds of latency, burning expensive tokens on deterministic tasks and causing queue congestion.
Task-aligned model specialization. Fast, typed small models execute classification and extraction in milliseconds, reserving frontier models exclusively for multi-step reasoning and ambiguous synthesis.
Operational telemetry shows that over seventy percent of internal agent turns do not require deep reasoning. Confirming date fields, converting raw email text into typed JSON payloads, or categorizing an inquiry as billing versus support can be solved deterministically by small vs frontier models agents at a fraction of the cost. Sending simple triage to a frontier model inflates token expenses tenfold and adds compounding latency to multi-turn execution loops.
- Wasted token budgets on binary decisions: Evaluating basic user intent with an oversized model requires transmitting large system prompts for simple yes-or-no classifications.
- Compounding latency across multi-step tools: When an agent executes sequential tool queries, a two-second latency per call accumulates into unacceptable delays for the end user.
- Elevated exposure to provider rate limits: Frontier models maintain tighter requests-per-minute quotas; relying on them for high-volume trivial turns introduces avoidable production throttle errors.
The First Triage Tier: Fast Small Models and Strict Schemas
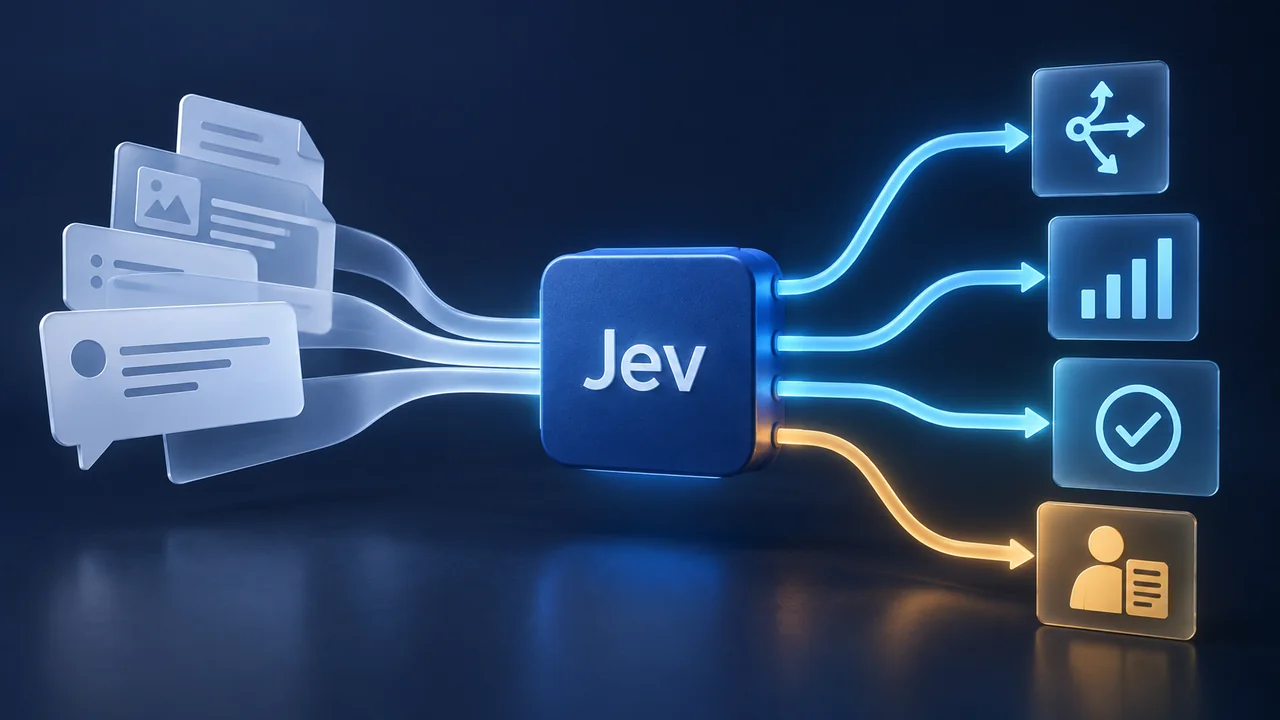
The foundation of effective model routing is an upfront triage gateway. This component does not make high-stakes commitments; instead, it acts as a high-speed traffic controller. Compact specialized models complete initial inspection within two hundred milliseconds at nominal token cost.
To ensure deterministic behavior, the small triage model must not output freeform conversational prose. Every call enforces a rigid JSON schema through structured output guarantees, constraining fields, data types, and enum values:
- Bounded intent enumeration: The model maps requests strictly to predefined category keys, eliminating hallucinated action types.
- Validated entity extraction: Key identifiers such as invoice numbers and customer emails are parsed into typed properties verified immediately in application code.
- Explicit confidence scoring: A calibrated confidence metric enables the router to detect borderline ambiguity and trigger escalation.
- Prompt injection screening: The lightweight tier sanitizes untrusted input and detects adversarial instructions before they can interact with privileged tools.
When to Invoke Frontier Models: Ambiguity, Planning and Synthesis
If compact models handle triage and parsing so efficiently, under what conditions should an agent invoke a frontier reasoning engine? The key criterion is ambiguity. Frontier models deliver their highest value when structured rules and rigid schemas cannot resolve conflicting inputs or orchestrate multi-system plans.
In production custom AI agent development, we establish explicit thresholds for escalating execution to frontier models:
- Reconciling conflicting cross-system records: When a supplier invoice clashes with purchase order line items and resolution requires interpreting commercial contract nuances.
- Dynamic multi-step tool choreography: Scenarios where the agent must evaluate unpredictable intermediate outputs from multiple APIs and dynamically adapt its execution plan.
- High-stakes contextual communication: Drafting delicate client correspondence, summarizing executive negotiations, or articulating adverse policy decisions where tone and context are paramount.
- Boundary exception recovery: Resolving edge cases flagged with low confidence by the triage tier or addressing unstructured requests that defy standard templates.
To determine the optimal frontier model for each task category, engineering teams rely on model benchmark evaluations that measure verifiable tool calling and practical reasoning rather than generic trivia benchmarks, ensuring teams pay for reasoning depth only where it directly improves workflow accuracy.
Prompt Caching, Latency Budgets and Resilient Fallbacks
Operating a heterogeneous multi-model architecture requires strict resource governance. Without deliberate safeguards, orchestrating multiple model providers can introduce latency variance and operational fragility.
Two engineering mechanisms are essential to stabilize multi-model routing in production:
Modern model providers support prompt caching for recurring system instructions and schema definitions. Structuring agent prompts so the invariant prefix remains static dramatically lowers input token costs and accelerates time-to-first-token.
Every turn in the execution graph enforces a hard time allocation. Triage steps are bounded to a maximum of three hundred milliseconds, while complex synthesis stages operate under strict timeout limits to prevent pipeline stalls.
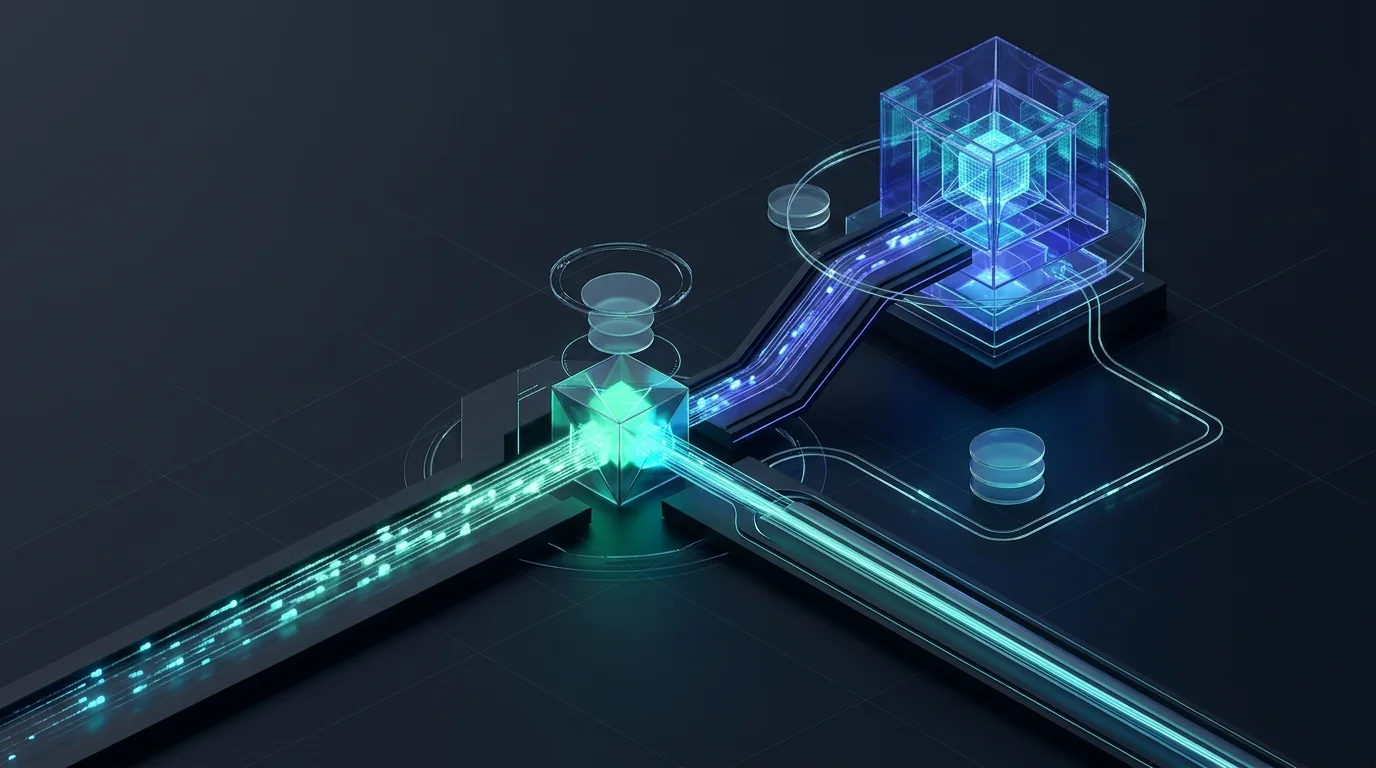
In addition to latency caps, resilient systems incorporate circuit breakers to maintain business continuity. If a frontier provider experiences elevated error rates or throttling, the router dynamically falls back to an alternative high-capacity model or routes the case to a human review queue with preserved execution traces.
Decision point in the illustrative scenario: how does the router handle a borderline confidence score from the triage tier?
When the triage model returns a confidence score below the configured operational threshold, the router does not guess an intent. Instead, it elevates the full conversation history to a frontier model tasked with assessing ambiguity. If uncertainty persists after reasoning, the agent asks the user a targeted clarifying question rather than firing an incorrect database mutation.
Practical Implementation: Building Routing into Your Agent Stack
To implement model routing without introducing technical debt into your codebase, follow four foundational architectural principles:
- Decouple routing logic from tool execution: The router functions strictly as a decision node that selects model parameters and context, keeping downstream MCP tools and database adapters completely model-agnostic.
- Track cost and latency telemetry per step: Measure the ratio of requests handled by small classifiers versus frontier models, monitoring token expenditures to continually reduce AI agent token cost.
- Maintain automated regression evaluation sets: Run curated golden test suites whenever updating classifier prompts or switching model versions to ensure triage accuracy never drifts.
- Expose tunable confidence thresholds: Treat escalation triggers as configurable runtime parameters, allowing operational teams to adjust the balance between cost optimization and reasoning depth.
Production agent reliability is never achieved by defaulting to the heaviest model, but by routing each subtask to the most efficient engine that can solve it reliably.
Combining fast typed classifiers for intake and extraction with frontier reasoning for ambiguity, supported by prompt caching and latency budgets, significantly lowers operating costs while delivering the speed and precision enterprise workflows require.